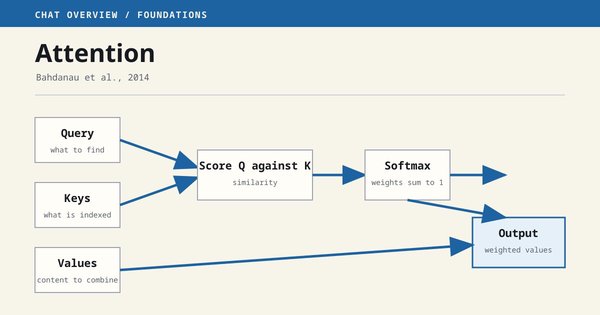
Attention Mechanisms: Bahdanau, Cho, and Bengio (2014)
How neural attention scores, weights, and combines input representations, from …
How neural attention scores, weights, and combines input representations, from …
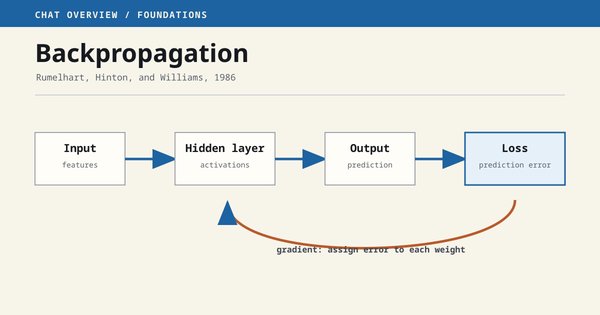
How backpropagation uses the chain rule to train multilayer neural networks, and …
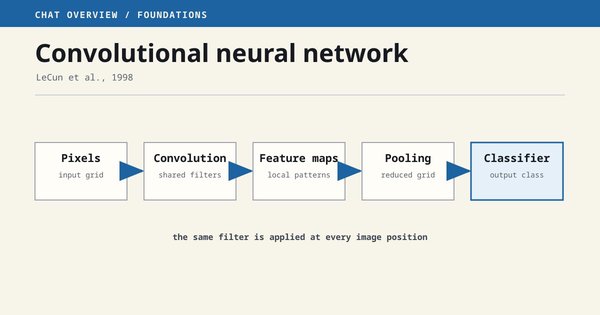
How convolution, shared weights, and pooling made LeNet-5 practical for image …
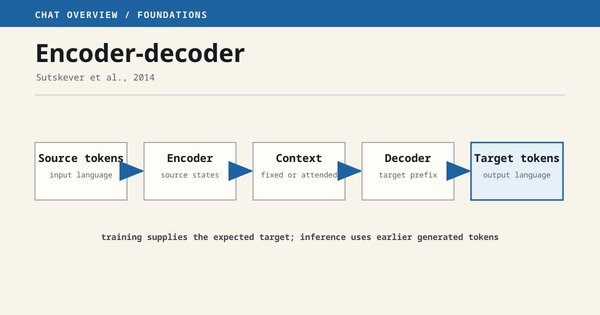
How encoder-decoder models map one variable-length sequence to another, from the …
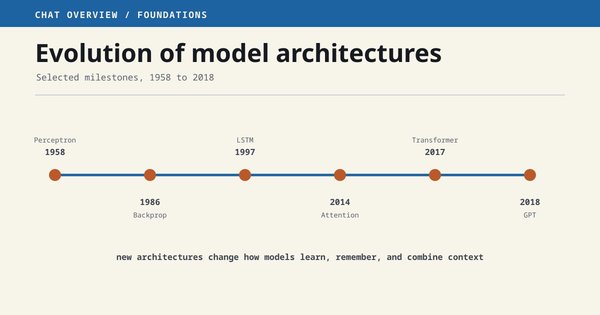
A practical timeline of neural-network architecture, from the perceptron and …
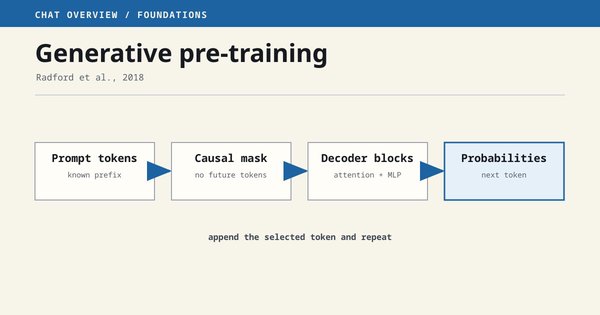
How GPT combines causal Transformers, next-token prediction, scale, prompting, …
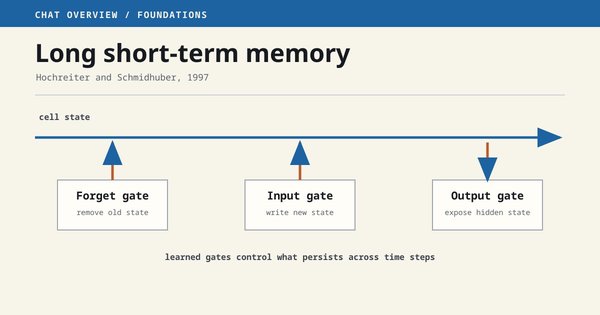
How LSTM cells use gated state to learn long-range sequence dependencies, and …
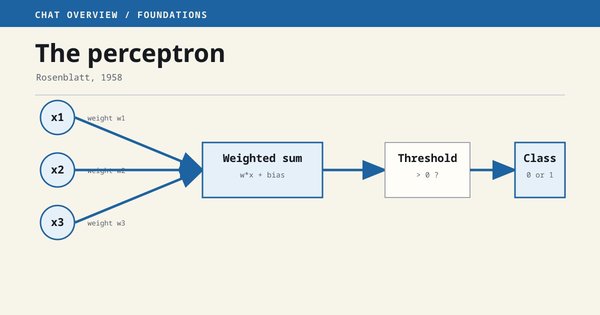
How Rosenblatt's perceptron learns a linear decision boundary, why convergence …
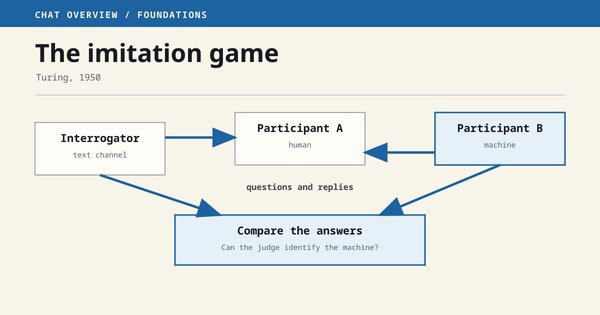
What Turing's 1950 imitation game actually tests, the objections the paper …
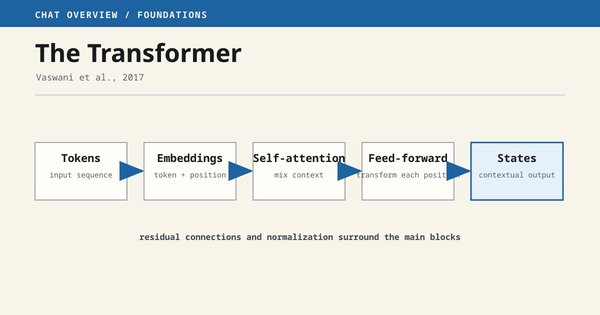
How the 2017 Transformer replaces recurrence with self-attention, including its …